Why two models, and why these two
The split follows what each model is actually good at. Casting, costume, set design and framing are still-image decisions, and they are cheap to redo as stills and expensive to redo as video. H3-Image is built for that stage: it generates at about 16 megapixels natively, edits with references, and follows detailed instructions, so a shot can be art-directed before any motion exists. LTX-2.5 then does the job stills cannot: movement, cuts and sound, in one pass, with the approved still as its starting frame. An Instagram roundup attributes the combined workflow, and a timing of just under five minutes per shot on one RTX 5090, to creator Kyo Kimura. That timing is a reported claim, not a benchmark, and nothing in this tutorial should be read as ALFW confirming it.
Before you download anything: the license map
This is the step most workflow posts skip, and it decides whether the rest of the tutorial applies to you. H3-Image's weights are published under MiniMax's community license, and its territory excludes the European Union, the United Kingdom, South Korea and the United States. If you are in one of those places, downloading and running the weights sits outside the license as written, whatever the download button allows. Organizations above US$1 million in annual revenue, and anyone offering the model as a hosted service, need separate permission on top of that.
Hosted services have separate availability and terms; this tutorial does not establish whether a particular reader qualifies for them, and separate prior authorization from MiniMax is another possible route. LTX-2.5 has no territory exclusion in its community license; its documentation summarizes the line as commercial, free under US$10 million in annual revenue. Read both license texts on the model pages before a production depends on either.
Step 1: Build the stills in H3-Image
Install ComfyUI and use the official H3-Image templates (text-to-image and edit) linked from the model card. On a 32 GB card, start from the community int8 build (diffusion model about 21 GB) rather than the 68.65 GB BF16 checkpoint; the model card's own local-deployment routes (SGLang, vLLM-Omni, diffusers) target server-class hardware. The configuration ALFW runs is a ComfyUI portable install with four model files from the model's Hugging Face repository: minimax_h3_image_pruned_int8_convrot.safetensors (20.98 GB, models/diffusion_models), qwen3vl_32b_minimax_h3_int8_convrot.safetensors (27.14 GB, models/text_encoders), qwen3.5_9b_w4a8_gptq.safetensors (7.34 GB, models/text_encoders) and minimax_h3_image_vae_fp16.safetensors (1.17 GB, models/vae), loaded through ComfyUI's built-in MiniMax H3-Image templates.
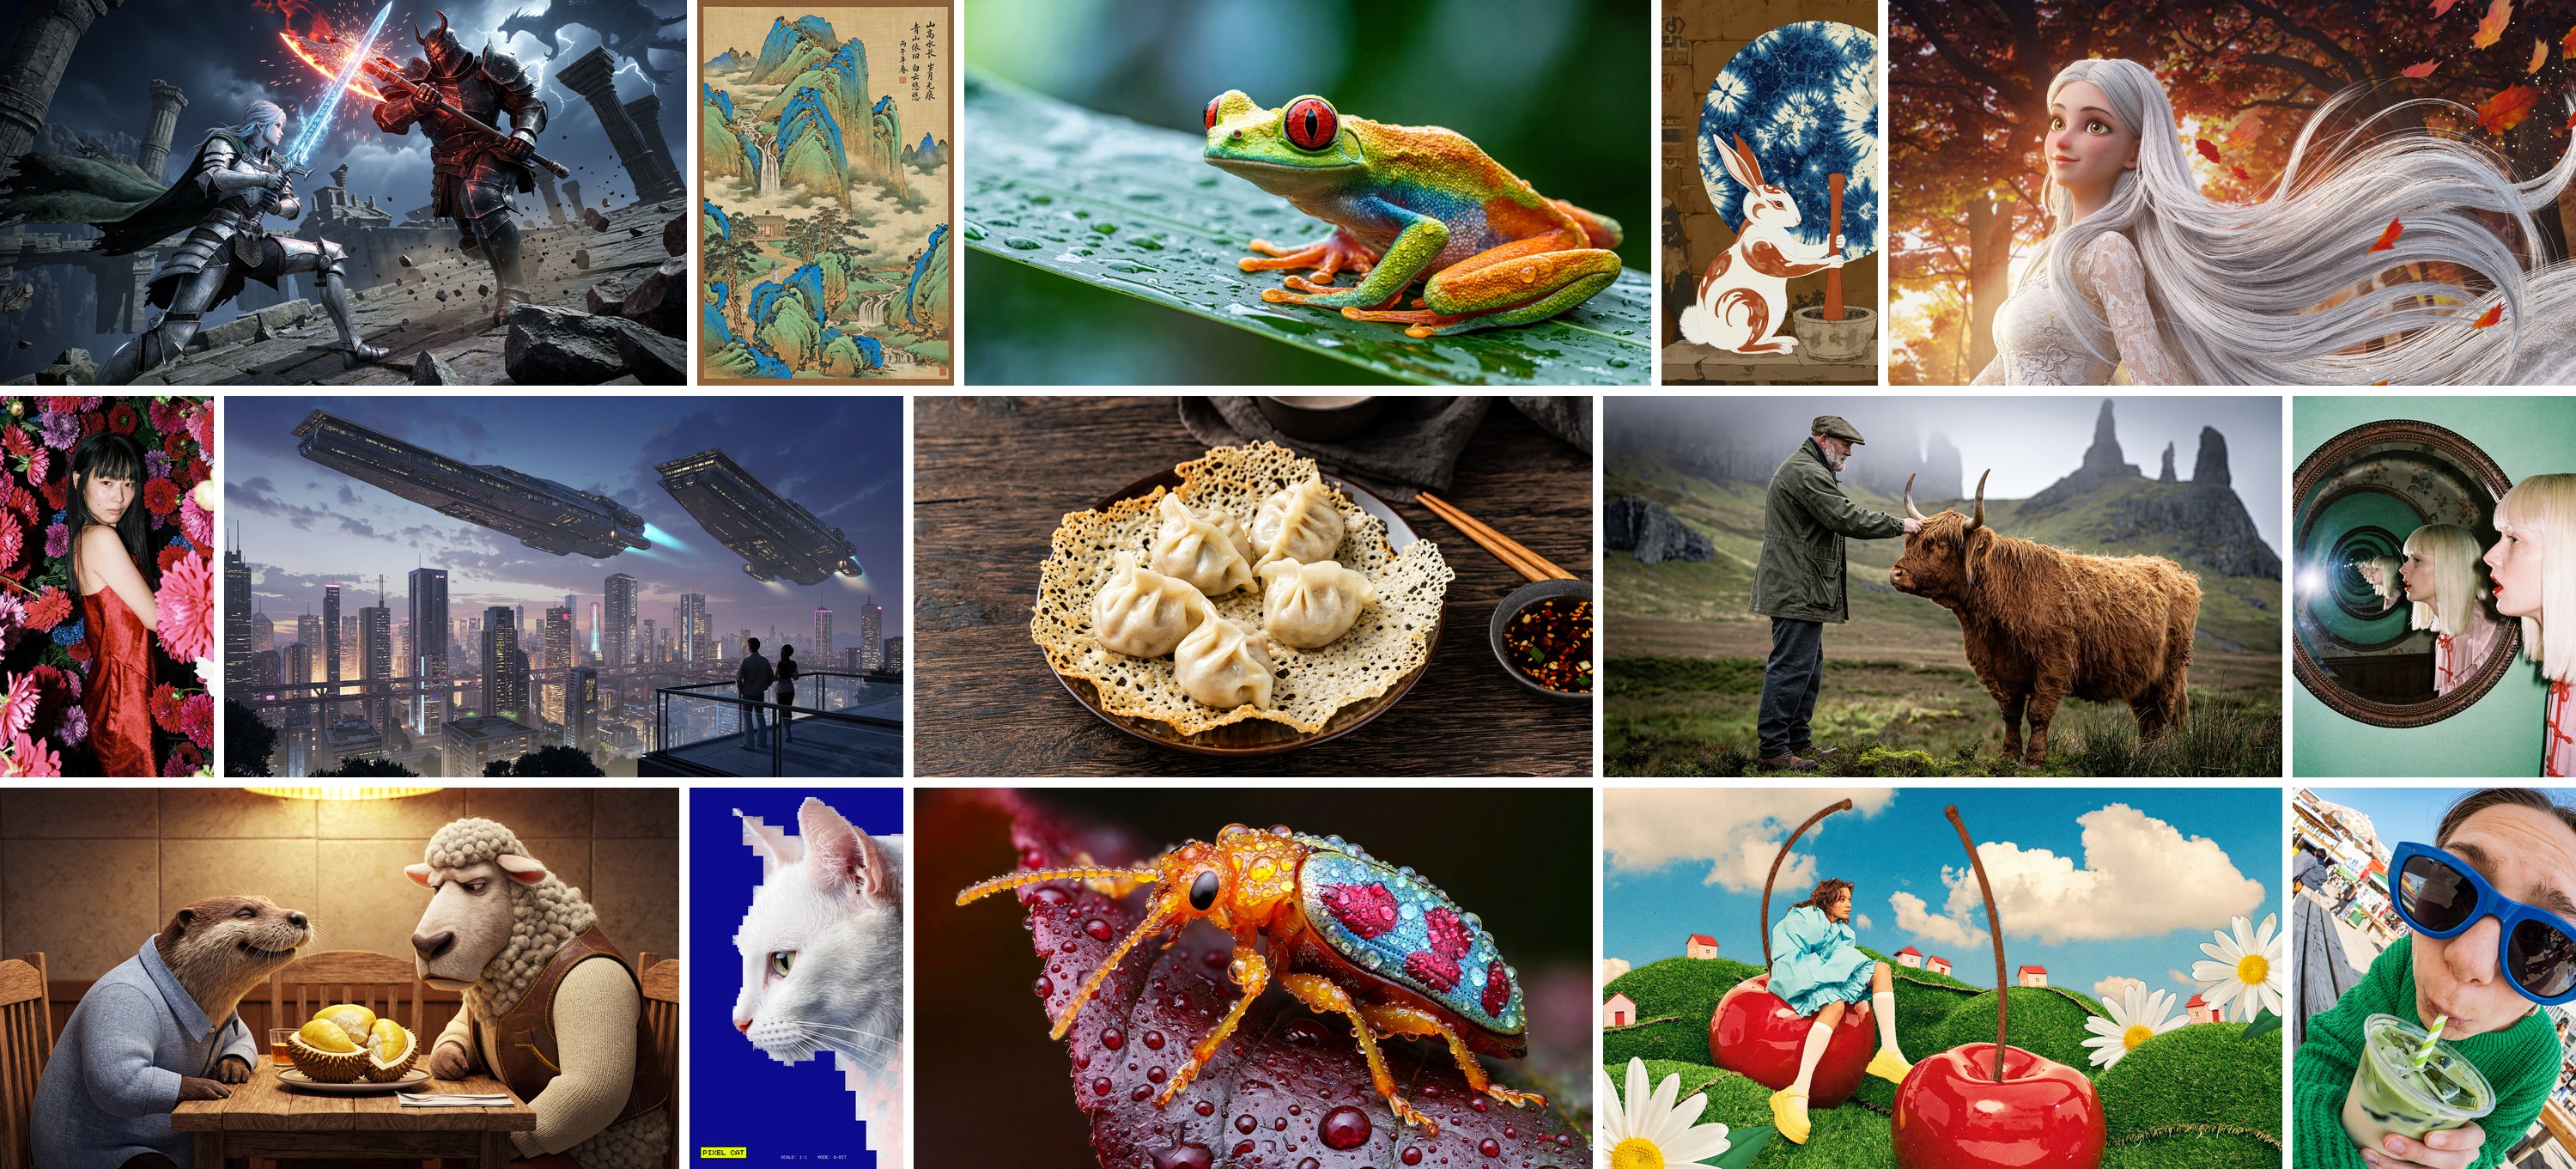
Work at delivery aspect from the start. For 16:9, generate at 5472×3072, the model's listed 16-megapixel size for that ratio, inside its best range of around 16 MP. Two parameter habits matter. The checkpoint is distilled to exactly 6 sampling steps with guidance fixed at 1, and the official templates are built around those settings, so leave both alone. And write prompts as a detailed description of the whole frame. The model expects a full scene description, and MiniMax ships an optional prompt expander (H3-Image-PE) for turning short prompts into one.
Generate the hero still for each shot: the frame you would freeze on a poster. Approve composition, faces and props here, where a redo costs seconds to a couple of minutes, not a video render. On ALFW's RTX 5090 the stills stage runs at about 21 seconds for a 16-megapixel text-to-image render and about 33 seconds for a 2048×1152 reference edit — generation execution time excluding model loading, from single observed production runs on our machine, not benchmark averages; your hardware and build will differ.
Step 2: Keep the cast consistent with references
Sequels to an approved still are edits, not fresh generations. H3-Image accepts up to 16 reference images in one edit and refers to them in upload order as <Picture 1>, <Picture 2> and so on, so a prompt can say, in effect, "the character from Picture 1, in the location from Picture 2, wearing the jacket from Picture 3." That ordering is the consistency mechanism this workflow relies on: build a small reference pack per character (face, outfit, one full-body shot) and reuse the same pack, in the same order, for every still they appear in.
Test consistency the way the careful reviewers do: preserve identity first, then check front, side and back views of the same subject, and only then judge style. A model that holds a face from the front and loses it in profile is showing you a risk to check before the still becomes a video's first frame, where fixing it costs a render instead of an edit.
Step 3: Animate in LTX-2.5, one shot or several
ALFW has not run this stage; what follows is LTX-2.5's own documentation, not our test results. In ComfyUI, LTX-2.5 ships with three native templates: text-to-video, image-to-video and first/last-frame. Access starts on Hugging Face: the repository is gated, so accept the LTX-2.x license there before the files will download; the model card's documentation and RunPod's setup guide (both in Sources) are the documented installation routes for this stage. For this pipeline the image-to-video template is the workhorse: load the approved still as the first frame and describe the motion, camera and sound in the prompt. Where a shot's ending matters as much as its start (a door fully open, a product facing camera), generate a matching final still in Step 1 and use the first/last-frame template to supply both ends.
For a short sequence, LTX-2.5's native multishot is the reason the workflow pairs it with the stills stage: one generation can contain several connected shots, and the model is designed to preserve character, environment, lighting and voice across the cuts, instead of stitching single shots and hoping the joins survive. Write the sequence chronologically in one prompt and name the cuts plainly. Respect the documented format rules while you plan: frame counts follow frames mod 8 = 1, dimensions must divide by 32, and a single generation runs 6–20 seconds. A one-minute short is therefore three to ten generations, before trimming, retries or editing time.
Two resource habits keep a single-GPU setup stable. Run the stages in sequence, H3-Image unloaded while LTX-2.5 renders, because the two working sets do not fit comfortably in 32 GB together. And expect the first session to be downloads: LTX's guidance budgets about 100 GB of free disk for that model, and the H3-Image side adds its checkpoint plus a text encoder.
What the five-minute claim does and does not establish
The claim, as the roundup reports it, is that a shot moves from still to finished clip in just under five minutes on one RTX 5090. ALFW has not reproduced that result; the supplied account does not establish an end-to-end time budget including setup, retries and editing. Our own stills-stage measurements (about 21 seconds for a 16-megapixel still, about 33 seconds for a reference edit) cover only the first stage of the pipeline and cannot stand in for the combined timing. What would settle the claim is a published end-to-end run: named builds, named settings, untrimmed timings. Without such a run in the sources reviewed, treat five minutes as the workflow's advertisement, not its specification.
The honest reason to run this pipeline is not a speed record. It is that local generation avoids per-clip service credits (it still consumes hardware time and electricity), generation can run locally (check the selected nodes and integrations before assuming inputs remain entirely on-device), and approving every shot as a still before any motion is generated is a discipline that improves planning in any tool.
The practical angle: who this replaces, and who it does not
For prototyping, storyboards, pitch films and short-form experiments, a local pipeline changes the economics from per-attempt pricing to electricity and patience, and it removes upload limits and content queues from the loop. For deadline-bound client work, validate output resolution, quality, support and turnaround before choosing this untested combined workflow; its license map binds regardless of the answer. The strongest use is the one the workflow's own structure suggests: develop the film locally until every shot is approved, then decide, shot by shot, whether the local render is the final or a hosted model earns its fee.
Sources
- [1] MiniMax H3-Image model card (specifications, sizes, ComfyUI templates, deployment routes), Hugging FaceRead source
- [2] Lightricks LTX-2.5 model card and documentation (multishot, ComfyUI templates, VRAM and disk guidance, frame rules), Hugging FaceRead source
- [3] QuantSlant, "MiniMax H3-Image: Price, API, Test Results and Comparison" (community quantized build sizes, license survey, November 2026)Read source
- [4] RunPod, "LTX-2.5: Run the Open-Weights World Model on RunPod" (VRAM tiers, gated repository, template list)Read source
- [5] Inspiration (workflow report, not specifications): Kyo Kimura's workflow as attributed in an Instagram reel roundup, November 12, 2026Read source
- [6] ALFW, "MiniMax Claims 4K Images in Under 10 Seconds. The License Excludes the US." (H3-Image launch context, November 10, 2026)Read source