The number in the other company's post
Both companies published on the same day, and the two posts do not emphasize the same things. Hugging Face's post lists the rebuilt routing's results: capacity errors down 46%, time to first token improved 16.9%, throughput up 16.3%. OpenRouter's post gives the same three figures in one sentence and finishes it with a fourth: the routing cost 6.0% more per request in the same live experiment.
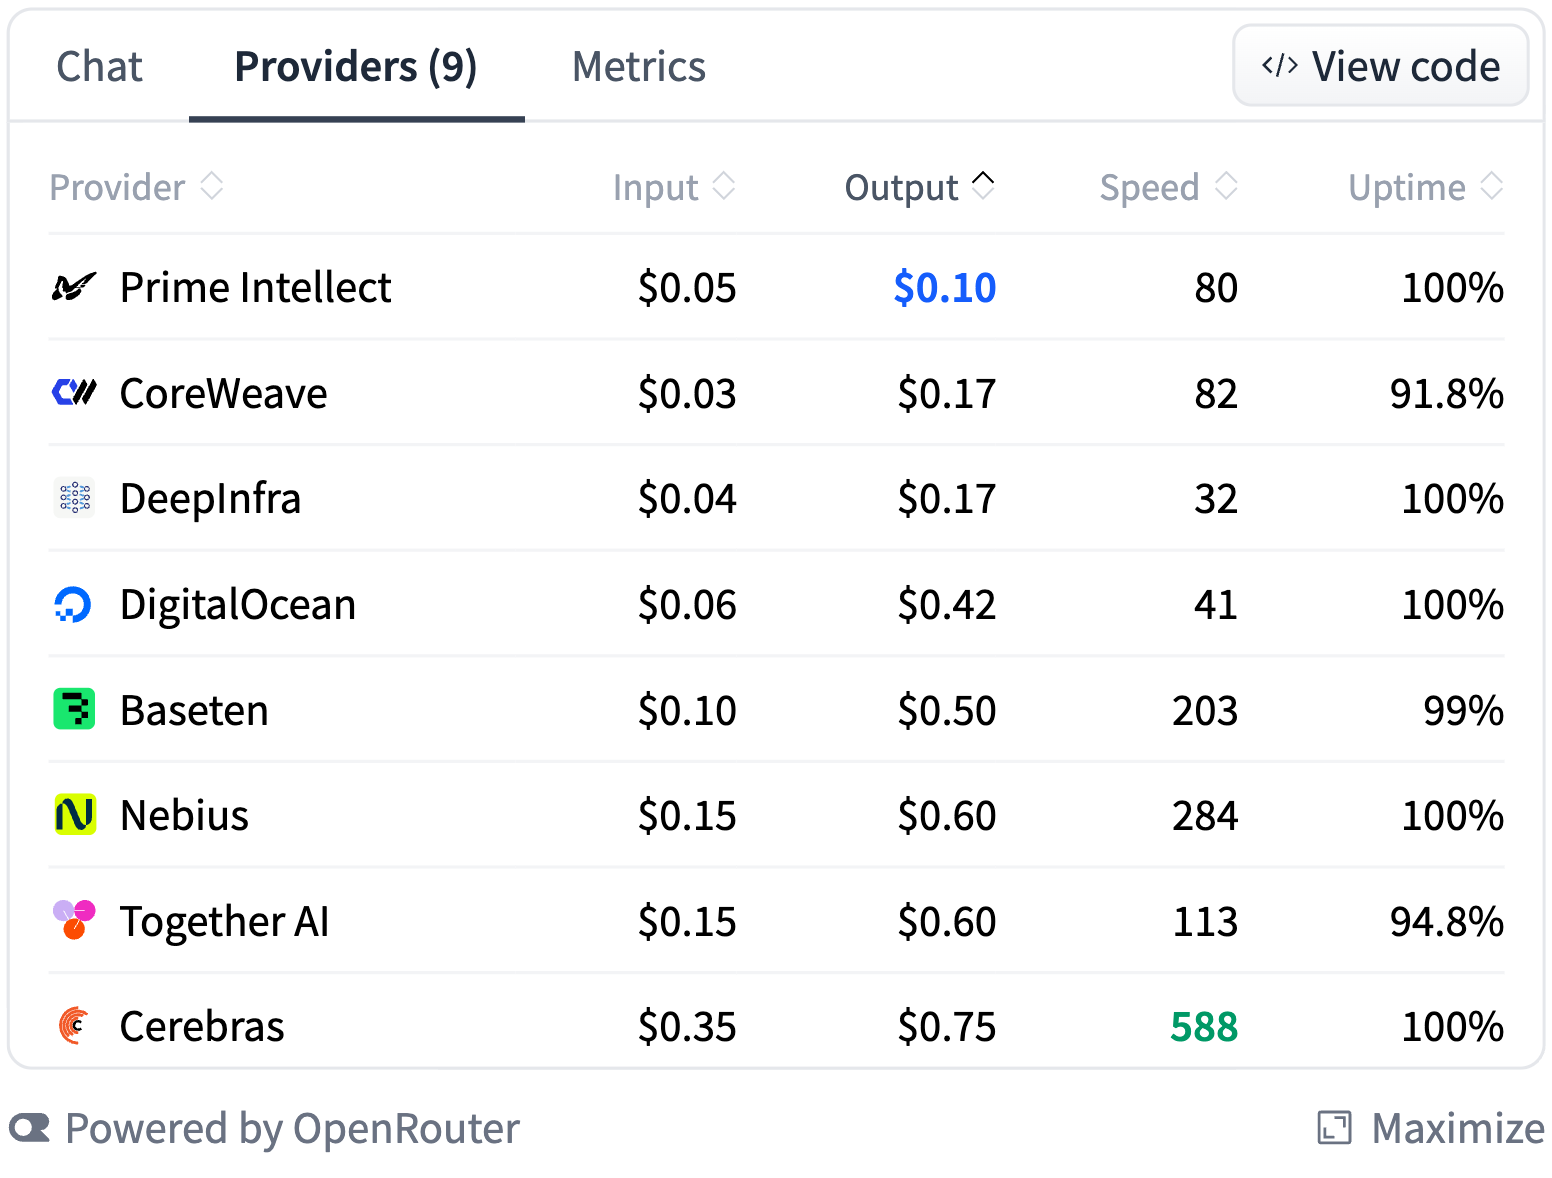
That does not make the trade a bad one. A failed request costs the caller latency and engineering time spent building failover that the router now supplies. But it is a trade, and a reader of only the Hugging Face post would not know there was a cost attached to the improvement. The figure is also an average from OpenRouter's own experiment on its own traffic. Hugging Face publishes no equivalent measurement for Inference Providers traffic, so nobody outside the two companies can yet say whether the same exchange rate applies here.
What the breaking change actually breaks
The change with the longest tail is labeled plainly in Hugging Face's post, under "Breaking change: custom provider keys." Language-model requests are now billed to the Hugging Face account or organization, so customers cannot authenticate these requests with their own provider keys. Teams holding negotiated rates, committed-use discounts or prepaid balances with a specific provider should treat those as arrangements to check, not benefits they can assume still apply through this route: neither post explains how existing provider-specific commercial arrangements interact with Hugging Face billing. What teams can still do is narrower: pin a provider with a model-ID suffix, or disable providers they do not want in settings.
Consolidation is the direction of travel here, and it has a logic. One bill, one token and one routing layer is simpler than a drawer of provider accounts. It also means a second company now sits inside a request path that used to have one. Hugging Face is explicit that it adds no markup. It does not say what OpenRouter earns from the arrangement, and neither post discloses the commercial terms between the two companies.
What stays the same, and what to check
Image, video and audio generation are untouched: they continue through Inference Providers directly, and Hugging Face states that custom keys for image and video providers keep working. The announcement covers Inference Providers routing; it does not announce changes to Inference Endpoints, Jobs or Storage Buckets. OpenRouter also describes a separate beta feature in the other direction: it can send request traces as JSON files — inputs, output, token counts and cost, with media left out — to a Hugging Face Storage Bucket the user owns, as raw material for evaluation or fine-tuning.
For a team already calling Inference Providers, the practical checklist is short. Confirm that nothing in the stack passes a provider key for a language model, because that path is closed. Decide whether the default routing policy is acceptable, or whether cost- or latency-sensitive models should carry a :cheapest or :fastest suffix. Then watch the new per-provider spend breakdown for the first billing cycle, because the 6.0% figure is an average from someone else's traffic, and the only version that matters is the one on your own bill.
Sources
- [1] Hugging Face, "Hugging Face and OpenRouter join forces to make open-weight models easy to run", November 16, 2026 (read first-hand by ALFW)Read source
- [2] OpenRouter, "OpenRouter Now Powers Inference on Hugging Face", November 16, 2026 (read first-hand by ALFW)Read source