A bandwidth target without an absolute baseline
Read the headline number closely. The L2000 is "planned to deliver more than twice the memory bandwidth of the MN-Core L1000 Series." That is a ratio, and a ratio is only as informative as its denominator. The release never states the L1000's bandwidth in gigabytes per second, and it schedules the L1000's release for 2027, so it provides no absolute figure or independent measurement a reader can check the target against. The L2000's own absolute bandwidth is not stated either.
So the announcement's central claim reduces to this: a chip that tapes out in early 2027 is planned to deliver more than twice the memory bandwidth of a different chip that is also due in 2027. Both sides of the comparison are plans. That does not make the claim false. It makes it unassessable from the announcement, which supplies neither absolute bandwidth values nor benchmark results with which readers can evaluate the target.
The rest of the specification sheet is similarly open. There is no process node for the Samsung Foundry logic die, no power envelope, no statement of how much DRAM each package carries, and no inference benchmark of any kind. For a development announcement made a quarter before tape-out, some of that is normal. It still means the release is evidence of a partnership and a schedule, not of a level of performance.
The stack is the product
The technical bet underneath the announcement is coherent. Generative AI inference is often limited by how fast weights and key-value data can be moved from memory to compute, not by raw arithmetic, and 3D integration of logic and DRAM aims to improve that data movement. PFN has worked on the MN-Core architecture since 2016, and supercomputers built on its first generation topped the Green500 energy-efficiency ranking three times, according to the release. This is not a company announcing its first chip.
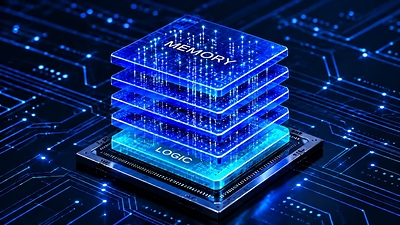
The execution risk sits in the stacking itself, and the release is unusually frank about where. PFN's chief executive names power consumption, heat dissipation and manufacturing yield as the hard problems in 3D-stacked development. SEMIFIVE's chief executive describes the L2000 as the company's "first full-scale 3D-IC initiative." Samsung Foundry is supplying not just manufacturing but the design infrastructure for connecting the dies. The Q1 2027 tape-out date is the first checkpoint: meeting it would establish that the design was handed off on schedule, not that manufacturing yield, functional success or performance followed.
What to watch
Three milestones will do more than any further announcement. The first is whether the L1000 ships in 2027 with a published bandwidth figure, because that number retroactively gives the L2000's "over 2x" a meaning. The second is the Q1 2027 tape-out itself: a tape-out that happens on schedule is evidence the 3D integration design work is converging, and a slip would be equally informative. The third is any absolute specification for the L2000, a bandwidth figure, a memory capacity or a power number, stated in units rather than multiples.
Until one of those lands, the accurate summary is narrow. Two companies with relevant backgrounds have agreed to build a memory-stacked inference chip, a Japanese government program is helping fund the underlying research, and the design is due at the foundry in the first quarter of 2027. The performance story is a target measured against a scheduled baseline.
Sources
- [1] SEMIFIVE / Preferred Networks, "PFN and SEMIFIVE Collaborate to Develop the MN-Core L2000 Series of Next-Generation AI Inference Chips" (PR Newswire, November 16, 2026; read first-hand by ALFW)Read source
- [2] MN-Core L Series product site, linked from the releaseRead source